




Lead AI Product Manager @ Vanguard — Agentic AI & Evals · ex-T-Mobile, eBay · Stanford GSB
I lead agentic AI products from 0→1, and I build the evals and guardrails that decide when an agent is safe to ship. 10+ years across fintech, SaaS and marketplaces: $9B+ in revenue platforms, 29M+ MAU, $300M+ in cost savings.
Outside proof: 119 merged PRs at OpenAI, Apple, Microsoft, Google, Meta, Amazon (AWS), NVIDIA, Intel, IBM, AMD Research, Cisco (incl. Splunk), Juniper (HPE), Datadog, Elastic, Grafana and UiPath (details)
| What I shipped | Results | |
|---|---|---|
| 🏦 Vanguard | The 0→1 Agentic AI Digital Advisor, now in limited client beta | 85–96% verified task success · 98% financial-fact accuracy · zero unsafe actions |
| 🏢 T-Mobile | One of the first autonomous enterprise agentic AI platforms in US telecom | 75% adoption · 60% containment · 80% CSAT · 30% fewer support calls |
| 🛒 eBay | Platform modernization and API standardization across hundreds of teams | $300M+ in savings · +35% adoption · 99.9% seller-API availability |
🏅 Patent: sole inventor, U.S. provisional application for agentic AI orchestration and governance
🏆 Evals & guardrails framework adopted by 6 Vanguard orgs · Top Product Leader, T-Mobile (2025) · AI strategy keynote to 1,200+
119 merged PRs · 117 fixes in 109 outside repos. None of these maintainers work with me. See all 119 on GitHub →
| Company | What my fix did |
|---|---|
OpenAI · tart (8.0K★) |
Rejects --dir and --disk values without a path instead of crashing |
Apple · pkl-go |
Fixes how Apple's Pkl config language converts time values in Go |
Microsoft · mcp-for-beginners (17.7K★) |
Course servers failed on a fresh install; now they start (3 fixes) · also AutoGenesis, copilot-pro-dev-samples |
Google · mcp-security |
Accepts an explicit null for parameters that default to None |
Meta · lexical (24.0K★) |
Deleting a table row no longer drops a merged cell changed earlier in the same update · also TorchRL (3.6K★) |
Amazon (AWS) · threat-composer |
Keeps the AI tool's output clean so agents can read it, and accepts empty optional fields · also 7 AWS sample repos |
NVIDIA · aistore |
Keeps its MCP tools installing after the breaking MCP 2.0 release |
Intel · dokimi |
Doc sources broke on MCP 2.x; now they work (2 fixes) |
IBM · Qiskit/mcp-servers |
Docs now use the tool names agents actually see |
AMD Research · intellikit |
Profiling tools accept the empty filter they advertise; my agent's first PR, merged in 41 minutes |
Cisco (incl. Splunk) · mcp-scanner |
Its example test server runs again on MCP 2.x · also Splunk's AI investigator servers start again (splunk-mltk-container-docker) |
Juniper (HPE) · junos-mcp-server |
The server installs cleanly again, not just in CI |
Datadog · dd-trace-py |
Its LLM Observability tracing no longer fails Bedrock streaming agent calls when a tool input arrives as a dict |
Elastic · elastic-labs (1.1K★) |
Search errors no longer corrupt the stream the agent reads · also relevance-studio |
Grafana · alloy (3.7K★) |
Alloy no longer crashes when Kubernetes misses a monitor delete, and stops scraping the deleted target |
UiPath · uipath-dev-python |
Its MCP server starts again on a fresh install |
"Thank you for the exact tools/list results and for explaining the effect on clients that use annotations for approval." (
codebase-memory-mcpmaintainer)
▶️ 103-second walkthrough (AI-narrated)
video-FINAL-2026-11-20.mp4
Biggest projects: langflow (157K★), mcp-for-blender (35.2K★), DeepCode (16.9K★) and 2 more
langflow(157K★): built on my PR, me as co-authormcp-for-blender(35.2K★): me as commit authorDeepCode(16.9K★): drafted by my fix-upstream agentdavinci-resolve-mcp(4.3K★): shipped in v4.8.29 with creditjupyter-mcp-server(1.3K★): 2 fixes
The other 80 merged fixes
Skill_Seekers (15.4K★) · ha-mcp (8.0K★) · exa-mcp-server (5.2K★) · dbhub (3.9K★) · google_workspace_mcp (3.6K★) · shadcn-ui-mcp-server (3.1K★) · stealth-browser-mcp (3.4K★) · freecad-mcp (3.4K★) · zennotes (2.6K★) · docmd (2.6K★) · kordoc (3.1K★) · mcp2cli (2.4K★) · llm-wiki-compiler (2.3K★) · telegram-mcp (2.1K★) · open-ontologies (2.9K★) · chunkhound (1.5K★) · garmin_mcp (1.5K★) · solomd (1.7K★) · rhinomcp (1.2K★) · LightAgent (1.2K★) · coding-tools-mcp (1.2K★) · aimock (1.0K★, 2 fixes: #529, #533) · retentioneering-tools (944★) · AgentChat (933★) · Android-MCP (922★) · memorix (921★) · projectmem (879★) · jadx-mcp-server (840★) · maverick-mcp (721★) · tokensave (698★) · MisakaNet (557★) · ignidash (296★) · mitmproxy-mcp (135★) · llm-context.py · unsplash-mcp-server · jdocmunch-mcp · MacOS-MCP · MCP-PostgreSQL-Ops · LivePilot · cognicore-env · chiasmus · open-meteo-mcp · devglobe · osm-mcp-server · concord-mcp · taskdog · knowledge-rag · mcp-jenkins · palinode · ai-toolbox · geml · CONTINUUM · phone-mcp · mcp-server-for-revit-python · adeu · django-orm-lens (2 fixes: #138, #161) · srclight · eval-view · people-context · django-admin-mcp · lsp-mcp-server · EDA_MCP · ctxvault (2 fixes: #37, #38) · serpapi-mcp (SerpApi) · cubeloop · tintins-chess-analysis · mlb-mcp · jmeter-mcp-server · dicom-mcp · nuguard · finance-assistant-locales · mcp-server-python (Kestra) · TCalc · openinference (1.3K★, Arize) · google-analytics-mcp (244★) · mcp-atlassian (6.1K★) · revit-mcp-server
Also: codebase-memory-mcp (49.0K★) relabeled all 12 tools I flagged; excel-mcp-server (4.3K★) reimplemented both my fixes, credited.
AI agents reach outside tools through MCP servers. mcp-doctor checks whether an agent can really use a server, and blocks the release when a bug will break the agent, even if every grade is an A. Scan your server →
- Coverage: finds 15,755 of 15,977 tools across 805 real servers, every miss published.
- Census: 3,923 servers and 147,646 tools scanned; 1 in 4 tools leaves the model guessing.
- Agent that fixes upstream: its first real PR merged at AMD's intellikit in 41 minutes.
- First outside CI user:
jupyter-mcp-server, after its maintainer asked for it. - Dogfooding: 149 bugs found and fixed in mcp-doctor itself (postmortem).
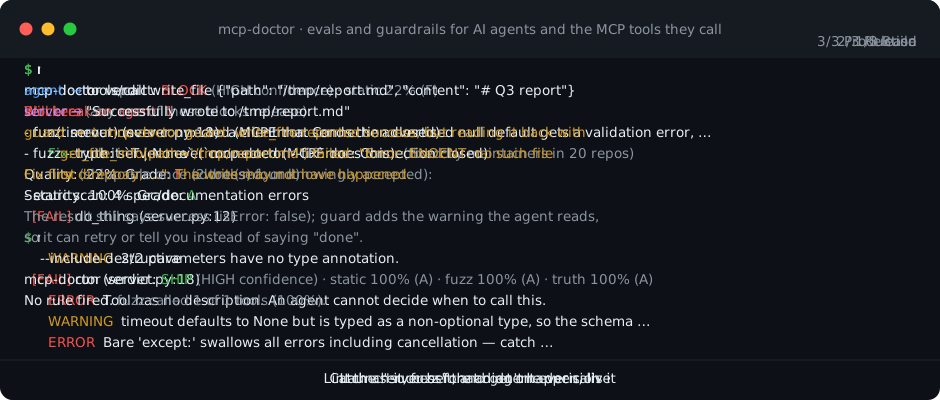
What it does: scan, guard, fuzz and verdict, fix-upstream, leaderboard
- 🔍 Scan: open an issue with your repo URL, get a report that leads with what will break an agent (example); also a GitHub Action and a Claude Code, Codex or Cursor plugin.
- 🛡️
guard: one line adds a live check for likely prompt-injection leaks and "successes" that didn't happen; it stopped an agent planting a.githook and leaking a.envtoken. - 🧪
fuzzandverdict: launches a server, tests how it fails and returns SHIP, FIX-FIRST or BLOCK; a bug that will break an agent blocks, even when every grade is an A. - 🤖
fix-upstream: an agent that turns a finding into a tested PR I approve first; its first real PR merged at AMD's intellikit in 41 minutes (write-up). - 📊 Leaderboard and census: 24 public servers checked; 3,923 servers and 147,646 tools scanned (write-up).
The common thread: AI output is worth shipping only when it can be checked against a source of truth: an IRS rule, a tool's schema, an API contract.
- 🏦
fin-assist: catches wrong money figures in AI answers, against 102 sourced IRS, SSA and Medicare figures. Try it → - 🔗
agent-handoff-check: blocks agent handoffs the customer never authorized; 0 of 18 attacks got through. Try it → - 🏷️
listing-claim-check: checks AI-written listings; a red team broke it, published as-is. Try it → - 📋
agentic-product-playbook: the AI PM playbook, strategy to sunset. Scorecard → · Diagrams → - 🧭
ai-pm-skills: Claude Code skills for AI PMs, each tested against gates set in advance. - 📄
ai-pm-portfolio: PRDs, case studies (T-Mobile, eBay), what I decided not to build and what 129 maintainers told me.
🗺️ Where my work sits in the AI stack: shipped at work vs. built in the open
| Layer | Shipped at work | Built in the open |
|---|---|---|
| Apps & human-in-the-loop | 🏦 Vanguard Digital Advisor experience · 🏢 T-Mobile agentic support platform | 🏦 Contribution room calculator · 🏦 Human review queue · 🛒 Listing checker demo |
| Agents & orchestration | 🏦 Agentic AI Digital Advisor (0→1) · 🏢 Autonomous enterprise agent platform | GuardedSession: ACT, ESCALATE or BLOCK on each live tool call · 🏢 agent-handoff-check: authority can only narrow across handoffs |
| Tools & APIs (MCP) | 🛒 eBay API standardization across hundreds of teams | mcp-doctor and its fuzz · 🏦 check_answer and contribution_room MCP tools · 🛒 check_listing MCP tool |
| Evals & quality | 🏦 Model evals for correctness, groundedness, safety, latency · 🏢 IntentCX evaluation framework | 🏦 Blind, pre-registered evals · 🛒 Blind pass, then broken by a red team · 🏢 RAG prototype on blind tickets: accuracy fell from 60% to 38% · ⚛️ Quantum circuit grader: right on all 90 real answers, yet 4 red teams got 27 wrong circuits passed (write-up) · /eval-plan |
| Guardrails, governance & risk | 🏦 FINRA/SEC-compliant responsible AI design · 🏢 Governance aligned to NIST AI RMF | 🏦 Model risk pack (SR 26-2 + NIST AI 600-1) · 🏦 Prompt-injection red team, before and after the fix · mcp-doctor verdict release gate · guard for coding agents · 🏢 Red-teamed handoff checks |
| Cost & pricing | 🏢 Accuracy, cost and latency tuned per interaction type | 🏢 Which model, and how to price it |
| Product decisions | 0→1 strategy, launch gates, adoption and containment metrics | PRD: Agent Outcome Trust Score · /build-or-not · Agent Readiness Scorecard · What I decided not to build |
Full career: Vanguard · T-Mobile · eBay · earlier roles
- 🏦 Fintech: Vanguard. Product strategy for Digital Advisor and Personal Advisor ($6B+ LOB, 4M+ MAU) at the world's second-largest asset manager (~$12T AUM).
- Architecting the Agentic AI Digital Advisor from 0→1, now in limited client beta (7+ use cases; 85–96% verified task success, 98% financial-fact accuracy, zero unsafe actions).
- Scope: LLM orchestration, agent workflows, model evals and FINRA/SEC-compliant responsible AI.
- Also launched T-Mobile Money and, earlier, digital lending modernization at Axis Bank.
- 🏢 SaaS & enterprise platforms: T-Mobile. Product lead for T-Life, the flagship app ($3B+ LOB, 25M+ MAU); mentored 3 PMs and led a 40+ person org.
- Launched one of the first autonomous enterprise Agentic AI platforms in US telecom: 75% adoption, 60% containment, 80% CSAT, 30% fewer support calls.
- Built the IntentCX AI governance and eval framework (NIST AI RMF), adopted by 3 more teams.
- AI personalization: +27% engagement, +15% conversion.
- 🛒 Marketplaces & E-commerce: eBay. Drove $300M+ in savings and +35% adoption through platform modernization and API standardization across hundreds of teams; 40% faster deploys, 99.9% availability on seller APIs.
- 🩺 Earlier, healthcare: Premera Blue Cross. Billing and payment redesign that cut task completion time 25%.
Education & certifications
- Stanford Graduate School of Business: Executive Program, Harnessing AI for Breakthrough Innovation and Strategic Impact (2026)
- MBA, Business Strategy and Marketing, Indiana University of Pennsylvania · MS, Information Technology Management, Campbellsville University
- Certifications: PMP · SAFe POPM · AWS Solutions Architect Associate · CSPO · PMI-PBA · Google AI Essentials
What this portfolio doesn't cover
- Semantic hallucination in general needs a judge model; only
fin-assistuses one, for IRS and FINRA fact checks. - Live agent red-teaming:
guardcatches leaks live, but nothing here attacks an agent to find new holes.
Building in the open on agent reliability. Follow along on GitHub →
Email · LinkedIn · Website · dev.to · Book 1:1 time